


Ask a compliance director whether their team finds out about regulatory change on time and the answer is usually yes. Ask how long it takes to say what a given change means for the business, which obligations move, which policies need rewriting, and who owns the work, and the answer gets vaguer.
That gap is where most regulatory intelligence programmes lose money. Detection has largely been solved. Feeds exist, regulators publish, alerts arrive. The expensive part sits after the alert, in the interpretation and routing layer that almost nobody has instrumented, measured, or resourced properly.
This guide covers what regulatory intelligence is, the four structural problems widening the gap in 2026, how technology closes each one, and how to measure whether your programme is working. If you are already at the stage of scoping a platform, our regulatory intelligence software development page covers the engineering side in detail.
What is regulatory intelligence?
Regulatory intelligence is the systematic practice of tracking regulatory developments across the bodies that govern a business, assessing the specific impact of each development on that business, and delivering the result to the people accountable for acting on it. It spans the full path from a rule being published to a decision being owned inside the organisation.
It is worth separating three things that sometimes get used interchangeably.
- Regulatory information is the raw material: consultation papers, final rules, supervisory statements, enforcement notices.
- Regulatory intelligence is the assessment applied to that material for one organisation, in its markets, with its products and its control environment.
- Regulatory compliance is the outcome you can use as evidence afterwards in front of auditors, regulators, etc.
Most organisations are well supplied with the first, thin on the second, and judged entirely on the third. And the regulatory intelligence layer is the one that determines how much companies spend to stay compliant.
Regulatory intelligence vs regulatory change management
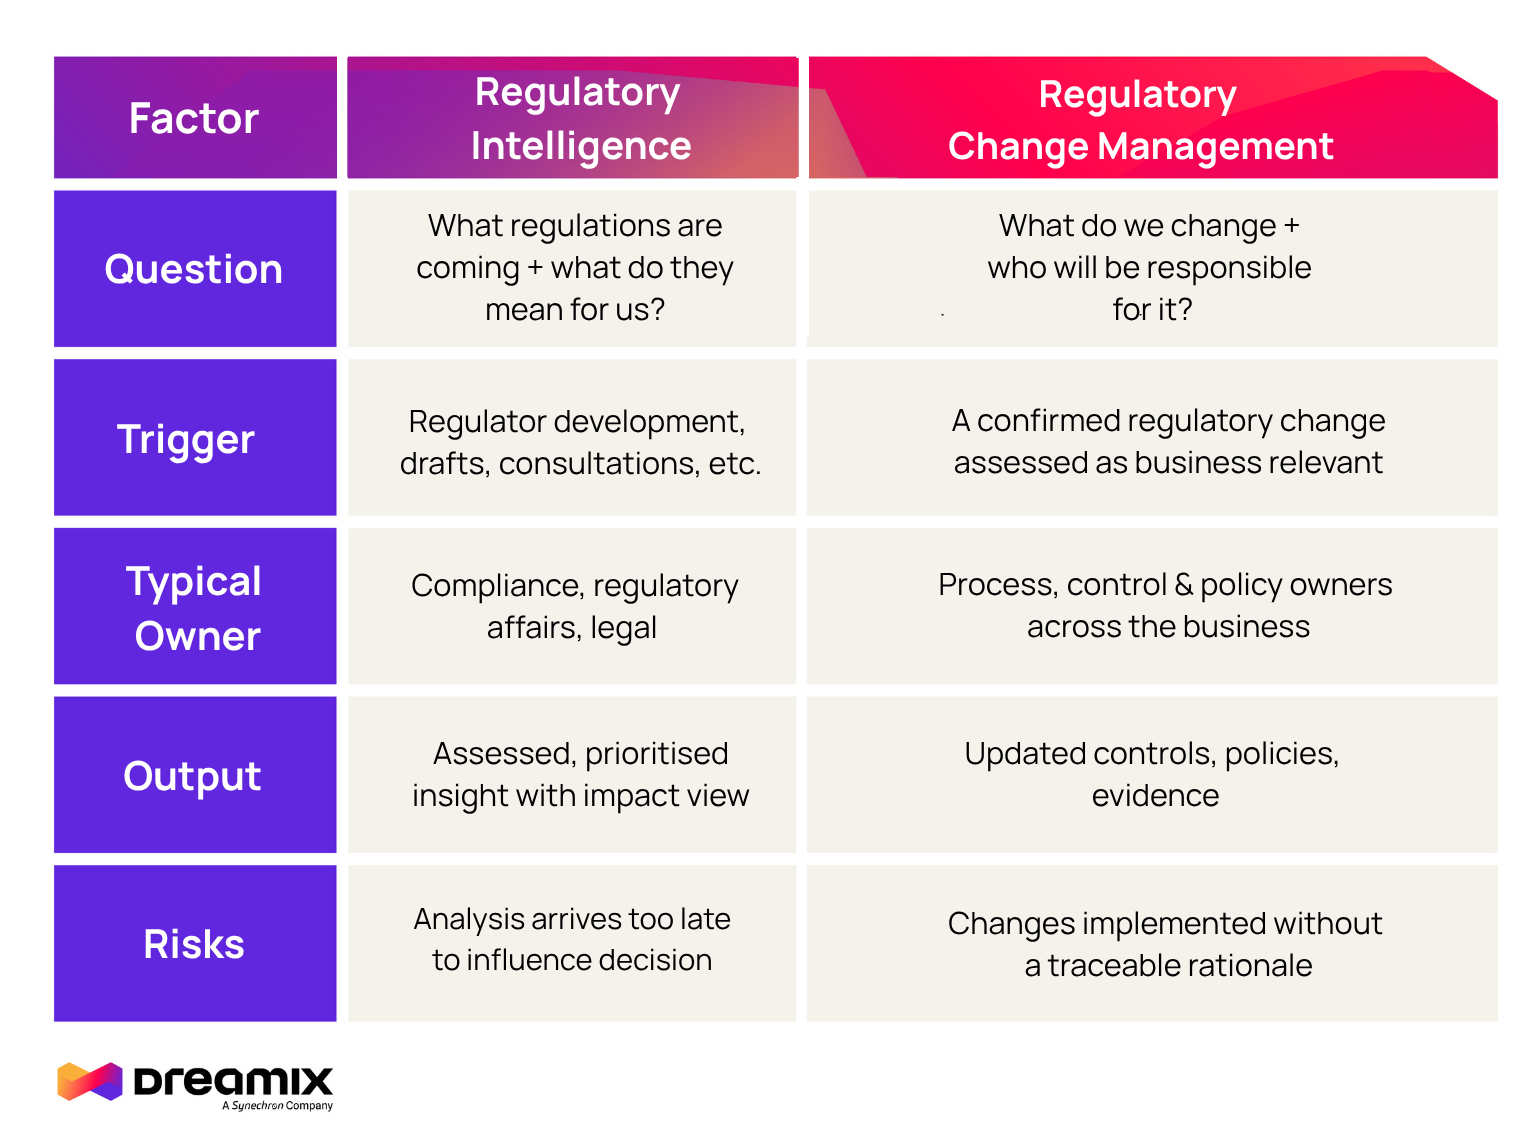
One further distinction decides who is accountable for what. Regulatory intelligence produces assessed insight. Regulatory change management consumes it and implements the result.
The simplification agenda will make this harder, not easier
There is a comfortable assumption circulating in boardrooms that regulatory pressure is easing. However, Deloitte's Financial Services Regulatory Outlook 2026 is direct about why that reading is wrong. Policymakers will seek to simplify and in some cases even deregulate, but that changes are expected to be selective, slow and fragmented, running alongside strengthened oversight in areas such as innovation, private markets and geopolitical risk. Their conclusion is a more complex, globally fragmented regulatory environment.
For a firm operating in one market, less rulemaking means less work. For a firm operating in eight, uneven simplification means eight regimes drifting apart at different speeds. Divergence is the expensive condition, because it removes the ability to write one obligation once and apply it everywhere.
The AI rulebook shows the pattern clearly. Gartner's top strategic predictions for 2026 and beyond note that more than 1,000 AI laws were proposed in a single year, with no two sharing a consistent definition of AI, and forecast that fragmented AI regulation will cover half the world's economies by 2027, driving around $5 billion in compliance investment. Every inconsistent definition is a separate obligation your team has to interpret, map and evidence.
Budgets are already moving in response. Gartner expects legal, risk and compliance functions to double their technology spend by 2027, and more recently forecast legal technology budgets doubling by 2028 as AI-enabled applications mature. Spend is not the constraint. Direction of spend is.
The three problems widening the interpretation gap
External fragmentation sets the pressure. Three internal failures decide how much that pressure costs you.
Problem 1: Regulatory data arrives in formats nobody can query
Regulatory content shows up as PDFs, portal pages, email bulletins, XML feeds and vendor summaries, in several languages, with no shared structure. Stored without versioning or lineage, it produces assessments that cannot be reproduced later.
McKinsey puts a number on the cost of leaving this manual. Firms running manual compliance processes often satisfy only a fraction of their obligations, and in one documented case a US bank's legacy system met 75% of requirements, rising above 95% after an automated approach streamlined data mapping. That 20-point swing came from data structure, not from hiring.
What technology changes: Ingestion pipelines normalise content into a structured, versioned regulatory library with full lineage. Every assessment can then be traced back to the exact text as it stood on the date it was made. For firms carrying older compliance systems, this is usually the point where legacy system modernisation becomes unavoidable, because the constraint sits in the data layer.
Problem 2: Obligations were never mapped to controls, so every change starts from zero
This is the most expensive problem and the least visible one. When obligations have never been decomposed and linked to the controls, policies and owners they govern, a regulatory change triggers a manual search. Someone asks around. Someone estimates. Someone escalates. The same ground gets covered again the following quarter.
Deloitte's research on the active regulatory agenda describes the compounding effect: heavy change volume forces firms to spend extensive resources interpreting new regulations, with a competitive job market, high turnover and undertrained resources making it worse. Every departure takes undocumented mapping knowledge with it.
What technology changes: An obligation model turns regulation into a queryable structure. A published change resolves to a named owner, a set of affected controls and a scoped piece of work, in minutes rather than weeks. The EU Anti-Money Laundering Regulation is a useful test case, because the obligations are known well in advance and the gap shows up as unmapped controls rather than missed news. Our AMLR readiness diagnostic walks through how to check an existing stack against it.
Problem 3: Evidence debt surfaces only under examination
Regulators increasingly want proof that a control operated, not confirmation that it exists. Organisations that manage regulatory change through email threads and shared spreadsheets can usually reach the right answer and still fail to show how they reached it. The gap appears at the worst possible moment.
What technology changes: an audit trail generated as a by-product of the workflow, rather than assembled retrospectively. The thread runs from published change through impact assessment to updated policy, with timestamps and approvals intact.
| Capability | Problem it solves | The question to ask your team |
| Horizon scanning | Volume arriving faster than analysts can read | Can we explain why an item reached a desk, and why three others did not? |
| Regulatory data management | Inconsistent, unversioned source content | Can we reconstruct what a rule said on the date we assessed it? |
| Obligation mapping | No standing link between rules, controls and owners | When a rule changes, does the system name the owner, or does someone start searching? |
| Policy impact analysis | Unknown blast radius of a single change | Can we show an examiner the full thread without assembling it by hand? |
AI now sits across all four, though the useful applications have moved. The first wave automated intake, classifying and tagging incoming change. The current wave assists interpretation: drafting impact assessments, surfacing affected policies, and cutting false positives so analysts review fewer items with higher hit rates.
McKinsey's guidance is to prioritise automating controls that are time-intensive, error-prone or repetitive, which describes regulatory impact analysis precisely. Dreamix’s expertise in AI and machine learning development and agentic AI in the regtech domain covers how these models get into production systems with the traceability regulated firms need.
Our capabilities in production
Dreamix team has built a production-ready AI platform for a leading compliance software provider that gives compliance teams one point of access to a large and growing library of regulatory sources, replacing the manual search across scattered systems described earlier in this guide.
Sectors that benefit most from regulatory intelligence
Regulatory intelligence matters most across financial services, where obligations are dense, cross-border and fast-moving.
- RegTech vendors: For regtech SaaS platforms, regulatory intelligence is often the product. Coverage breadth and jurisdiction expansion are competitive features, which puts the obligation model on the critical path of the roadmap rather than in the back office. More on our RegTech engineering work.
- Banks and capital markets: Capital, conduct, resilience and financial crime regimes overlap, with supervisory expectations that shift faster than release cycles. See our expertise in fintech software development.
- Insurers and InsurTech providers: Solvency reporting, product governance, consumer protection and data handling obligations move on separate cycles, each touching different parts of the policy and claims estate.
- Investment firms and asset managers: MiFID II, EMIR and related frameworks impose reporting, disclosure and transaction monitoring duties where the obligation detail sits deep in technical standards that update independently of the parent regulation.
- Fintechs, payment and lending providers: Growth into a new market adds a full regulatory regime rather than a feature, so the obligation model becomes a constraint on expansion speed. Identity and onboarding rules are a live example: see our breakdown of the eIDAS 2.0 timeline and business impact, and the EUDI Wallet compliance accelerator we built for it.
Five practices that separate mature programmes
Keep one regulatory record, versioned. Multiple partial libraries guarantee that two teams reach different answers about the same rule. Version history and lineage are what make an assessment defensible months later.
Map obligations before the next change lands. Building the obligation model during a live regulatory deadline is the most expensive way to do it. Firms that map in advance convert change into routine work rather than a fire drill.
Prioritise by business impact. Sorting by regulator or by publication date treats every item as equal. Scoring against exposure, revenue at risk and implementation effort puts scarce analyst time where it earns the most.
Apply AI to interpretation, not only to intake. Classification and tagging at the point of ingestion is now table stakes. The larger return comes from using language models to draft impact assessments, surface affected policies and cut false positives, with human review on the output. McKinsey's guidance on compliance in the AI era makes the same case, recommending that firms prioritise controls that are time-intensive, error-prone or repetitive when choosing what to automate.
Instrument the process. A function that cannot show its cycle times will lose the budget argument to one that can, particularly under the headcount scrutiny Gartner reports across legal and compliance departments heading into 2026.
Five metrics worth reporting to the board
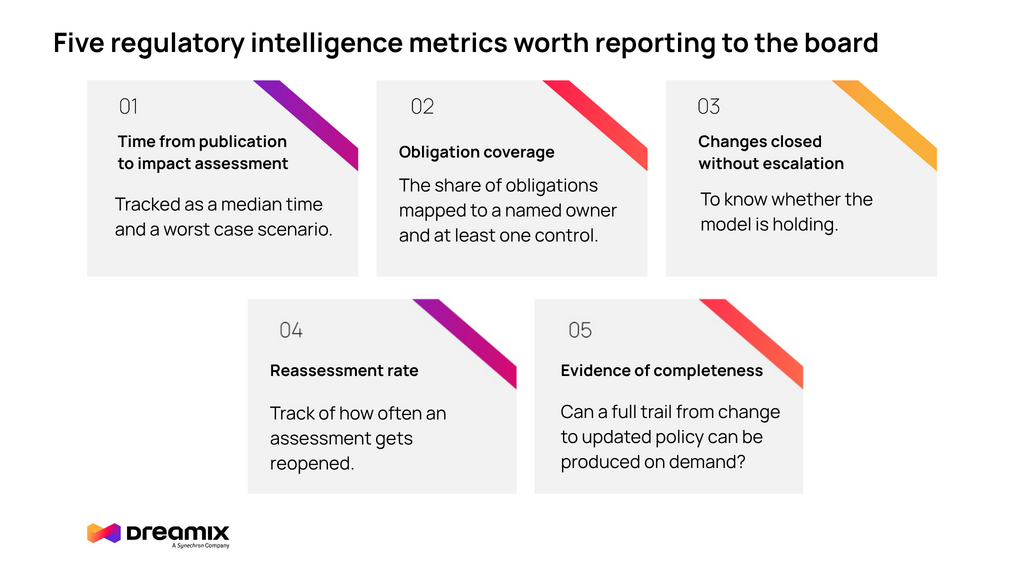
Most regulatory intelligence reporting counts inputs: sources monitored, alerts received, updates reviewed. Those numbers say nothing about whether the function is working. Five better ones:
- Time from publication to completed impact assessment, tracked as a median and a worst case.
- Obligation coverage, the share of obligations mapped to a named owner and at least one control.
- Proportion of changes closed without escalation, which shows whether the model is holding.
- Reassessment rate, how often an assessment gets reopened because it was wrong or incomplete.
- Evidence completeness, whether a full trail from change to updated policy can be produced on demand.
Build, buy, or both?
Off-the-shelf platforms cover standard regimes well. Building earns its cost when the obligation model is proprietary, when jurisdictions sit outside vendor coverage, or when regulatory intelligence has to run inside existing core systems rather than beside them. For RegTech vendors the question does not arise, since the platform is the product. Most firms land on a hybrid, and we cover that decision in depth in agentic AI in compliance: build, buy, or fall behind.
If the answer is build, the next question is who builds it. Domain knowledge matters more than headcount here, because an engineering team without regulatory context will model obligations as data fields and miss the interpretation logic entirely. Our comparison of fintech development partners sets out the evaluation criteria worth applying when shortlisting potential tech vendors.
You can find further insights on the topic of build vs buy software by our CTO Denis Danov.
What this means for the executive team
Regulatory intelligence is usually funded as insurance against penalties. The stronger argument is capacity. When obligations are mapped and impact analysis is partly automated, compliance stops absorbing senior time from product and operations every time a rule moves. That released capacity has a value, and it is easier to defend in a budget review than a fine that did not happen.
The organisations getting this right treat regulatory intelligence as an operating capability with owners, cycle times and a data model behind it while firms struggling treat it as a subscription.
If you are scoping a platform or extending one, we work on this problem daily with RegTech vendors, banks, insurers, investment firms and fintechs. Talk to us about a regulatory challenge you are trying to solve and we will map it to an engineering approach.
FAQs about regulatory intelligence:
We’d love to hear about your regulatory intelligence challenges and needs and help you meet your business goals as soon as possible.


