Two pressures are compressing enterprise budgets at once in 2026. Margins are tightening, and the cost of keeping pace with technology is climbing faster than most planning cycles assumed. Deloitte's Q1 2026 North American CFO Signals survey found 52% of CFOs at organisations with at least $1 billion in revenue naming cost management as their most worrisome internal concern, the top response, up from 47% and third place six months earlier. The two forces they identified as driving it were pressure to invest in new technologies and declining profit margins.
Simultaneously, the spending curve’s interesting to observe as Gartner expects worldwide IT spending to reach $6.37 trillion this year, a 14.2% rise driven largely by AI infrastructure and cloud services. Very few companies are forecasting 14% revenue growth to match it. That gap is the core of the problem, and the cloud bill is where it surfaces first, because it is the one significant IT cost that grows every day without anyone signing a purchase order.
By now, most executive teams asking how to reduce cloud costs have already been through one optimization push. Someone deleted the orphaned volumes, bought a few reserved instances, and the bill dipped for a quarter. Then it climbed again, faster than before, and now there is an AI line item nobody can explain to the board.
The eight strategies for reducing cloud costs described below are ordered the way we sequence them with our partners: fastest payback first, structural changes after, so the savings from the early moves fund the harder ones.
What actually makes up a cloud bill
Six categories cover almost every line item. The proportions vary by workload, but the vocabulary is the same across AWS, Azure and Google Cloud.
- Compute. Virtual machines, containers and serverless functions. Usually the largest single line, and billed for the time a resource exists rather than the time it does useful work.
- Storage. Charged per gigabyte per month across performance tiers. Snapshots, backups and log archives accumulate quietly, because deleting them is nobody's job.
- Data transfer. Moving data out of a provider, between regions or between clouds. Priced per gigabyte and easy to miss until an architecture decision makes it large.
- Managed services. Databases, message queues, Kubernetes control planes. A premium paid to avoid operating them, which is usually money well spent.
- AI and accelerated compute. GPU capacity and per-token inference charges. The newest category and the least governed.
- Commitments, licences and support. Reserved capacity, marketplace software and provider support tiers.
A seventh category has no owner at all. McKinsey lists unallocated IP addresses, orphaned network interfaces, backups and snapshots belonging to systems that were retired long ago, all still billing every month.
Why cloud bills keep growing after the first optimization push
Three mechanisms undo a first-round cost programme, and they are worth naming because each one calls for a different fix.
Waste regenerates: Provisioning happens every day; optimization happened once. Thus, deleting idle resources in March does nothing about the ones created in April, so the saving erodes at the same speed engineers create new infrastructure. In a team shipping weekly, that usually means the bill is back near its old level within two or three quarters.
A new cost class arrived mid-programme. Deloitte's Tech Trends 2026 notes that token costs have fallen roughly 280-fold in two years, yet some enterprises are still receiving monthly bills in the tens of millions, because cloud usage grew faster than unit prices fell. Inference behaves unlike anything the original programme was designed around: it scales with customer usage, so a successful launch raises the run rate permanently rather than temporarily.
The people creating cost do not carry it. This is the reason the first two persist. McKinsey reviewed more than $3 billion in cloud spending across industries and found most organizations had 10% to 20% in untapped savings still sitting in their bills, including organisations that already had a dedicated FinOps team. The firm's explanation is straightforward: engineers usually lack both the incentive and the access to act on cost, so optimization loses to feature work, resilience work and security work every sprint. For a company spending €20 million a year, that unclaimed 10% to 20% is €2 million to €4 million of margin buying nothing at all.
How to reduce cloud costs: 8 spend optimisation strategies
1. Measure cost per business unit, not cost per service
A bill organised by service tells you that compute went up. It does not tell you whether that was good news. Pick two or three unit metrics that your commercial team already recognises: cost per transaction, cost per active customer, cost per claim processed, cost per flight scheduled. Track them monthly alongside revenue.
This single change alters the conversation at board level. Spend rising 30% while cost per transaction falls 15% is a growth story. Spend flat while cost per transaction rises is a warning that needs engineering attention. Without the denominator, every cost discussion defaults to "cut 10% across the board", which usually removes headroom from the systems that earn the most.
The bill grew by €360,000 and the business became cheaper to run at the same time. A board reading only the first row sees a 30% overrun and cuts the budget of the team that just improved gross margin.
Now hold the volume flat. Same €1.56m in Q4, still 40m transactions, and cost per transaction rises to €0.039, up 30%. The spend line is identical in both cases. The verdict is the opposite, and the second one calls for an engineering investigation rather than a budget cut.
2. Take the idle hours out first
Idle hours are the time your infrastructure is switched on and charged for while nobody is using it. For instance, a test environment that a team touches between 9am and 6pm on weekdays is genuinely in use for about 45 hours a week but can actually be billed for all 168. You are paying for roughly a quarter of what you get, and the cloud provider has no way to know the difference, because it charges for the calendar rather than for the work.
The usual sources, in order of how much they typically cost:
- Non-production environments running around the clock: Development, test, staging and demo systems that only matter during working hours, billed through every night, weekend and holiday.
- Log retention left at the default: Providers ship generous defaults, often years. Most teams never change them, so diagnostic data nobody will ever open is stored and paid for indefinitely.
- Forgotten snapshots and backups: Copies taken before a release or a migration and kept in case something went wrong, still charged per gigabyte long after the risk passed.
- Unattached IP addresses and network interfaces: Networking components left behind when a server was deleted. Each one costs very little; several thousand of them do not.
3. Move cost policy into the delivery pipeline
Monthly cost reviews find waste after it has been paid for. The alternative is to enforce cost rules at the point where infrastructure is defined, which McKinsey calls FinOps as code. The firm estimates the approach represents around $120 billion in value at global IaaS and PaaS spending levels.
A workable pattern uses three policy tiers on every pull request:
- Inform: flag a managed database service as a cheaper option than a self-managed one.
- Warn: alert when an autoscaling group is missing, without blocking the merge.
- Block: stop a deployment that provisions above a set threshold in a development environment.
McKinsey notes that organisations only need ten to fifteen policies early on. The engineering benefit matters as much as the savings: developers see the cost consequence of a design decision before it ships, rather than three weeks later in a spreadsheet they did not write.
Read next: Cloud Application Development Services to explore where cost ownership fits into a modern delivery setup.
4. Right-size against real telemetry, then re-run it quarterly
Right-sizing usually delivers a mid-teens percentage reduction on compute, and it usually decays within two quarters because workloads change and nobody re-runs the exercise. Treat it as a recurring job, not an event.
Two conditions make it safe. First, base decisions on observability data covering peak periods, not on averages. Second, agree with the business which services carry a performance guarantee, so engineers stop over-provisioning defensively to protect an SLA nobody has actually quantified. Always provision based on your metrics. It's reasonable to put higher resources first but unreasonable to leave it just because it's working.
5. Commit capacity deliberately, against a baseline you trust
Reserved instances and savings plans offer the largest headline discounts available, and they are also the easiest way to lock in a mistake. Committing to capacity for workloads you are about to re-architect converts a variable cost into a fixed one at the worst possible moment.
The sequence that works: right-size first, establish a stable demand baseline over 60 to 90 days, then commit to the portion of that baseline you are confident will still exist in twelve months. Leave the volatile top layer on-demand or on spot capacity. Review commitments before every migration wave, not after.

6. Treat data gravity and egress as an architecture decision
Data movement charges rarely appear in the first optimization review and often become the largest structural cost in the second. The exposure is growing: Gartner predicts that by 2030, more than 60% of enterprises will run intensive AI model activity in one cloud while their data sits in another, up from under 10% today. Every one of those pairings has a data transfer bill attached.
Decisions about workload placement, data residency and portability belong in architecture review, not in a procurement negotiation. Teams weighing this trade-off usually benefit from reading our guidance on cloud-agnostic development before committing to a provider-specific data path, and our 7-step multicloud deployment approach if more than one provider is already in play. Where analytics workloads dominate the bill, consolidating fragmented pipelines onto a single platform, as we describe in our overview of the Databricks Data Intelligence Platform, often removes more cost than tuning the individual jobs.
Read next: where our CTO Denis Danov breaks down the pros, cons and best practices of cloud-agnostic development
7. Give AI workloads their own cost line and their own controls
AI spend behaves differently from the rest of the estate. It is bursty, it is often provisioned outside standard procurement, and its business value is frequently unmeasured. Gartner surveyed 782 infrastructure and operations leaders and found that only 28% of AI use cases fully succeed and meet ROI expectations, while 20% fail outright. Unmeasured inference cost is how a successful pilot becomes an unprofitable feature.
Practical controls that work today:
- Route requests by task complexity so that smaller models handle the routine volume.
- Cache aggressively at the prompt and response layer.
- Set hard token and spend ceilings per environment and per team.
- Audit deployed endpoints monthly and retire the experiments nobody uses.
- Report cost per AI-assisted outcome, not cost per model.
For high-volume, steady inference, the deployment location itself becomes a financial decision. We compared the options in AI cloud setup: on-prem versus hybrid, which is worth reading before signing a multi-year commitment for GPU capacity.
8. Fix the workloads that were lifted and shifted
The most expensive cloud workloads in most enterprises are the ones that were moved without being changed. A monolith that scales vertically, keeps sessions in memory and holds an idle database connection pool costs several times what its refactored equivalent costs, and it will keep doing so until someone changes it.
This is the slowest move on the list and typically the largest. It also needs a business case per application rather than a blanket mandate. Some systems deserve refactoring, some deserve replatforming, and some should be left alone until they are retired. Our practical guides to migrating legacy applications to the cloud and migrating applications to the cloud set out how to make that call per system, and the cloud migration checklist for enterprise CTOs covers the governance around it. Where the cost sits in the data layer rather than the application layer, how to do data migration is the more relevant starting point.
Practical cloud cost reduction roadmap: 90-day sequence
| Weeks | Focus | Typical outcome |
| 1 to 4 | Unit metrics defined, idle and orphaned resources removed, non-production schedules applied | 5% to 8% off the monthly bill, plus a baseline everyone agrees on |
| 5 to 8 | Right-sizing on telemetry, cost policies added to CI/CD, egress mapped | Another 8% to 15% on compute, with waste no longer recurring |
| 9 to 12 | Commitment strategy set against the new baseline, AI workloads separated and capped, refactoring business cases prepared | Discount coverage locked in on stable demand only, and a funded roadmap for the structural work |
The 10% to 20% McKinsey range is reachable within a quarter for most organisations. Holding it for three years is the harder part, and that depends entirely on whether cost ownership sits with the engineering teams making daily design decisions.
3 mistakes that can undo the savings
Cutting before measuring. A 10% across-the-board reduction removes capacity from the systems that generate revenue as readily as from the ones that waste it. Unit metrics first.
Making FinOps a reporting function. A team that produces dashboards but cannot change infrastructure will document the problem accurately for years. Give cost policy the same enforcement path as security policy.
Buying commitments to hit a quarterly target. Discounts applied to workloads scheduled for re-architecture are the most common self-inflicted cost problem we encounter.
Where Dreamix fits
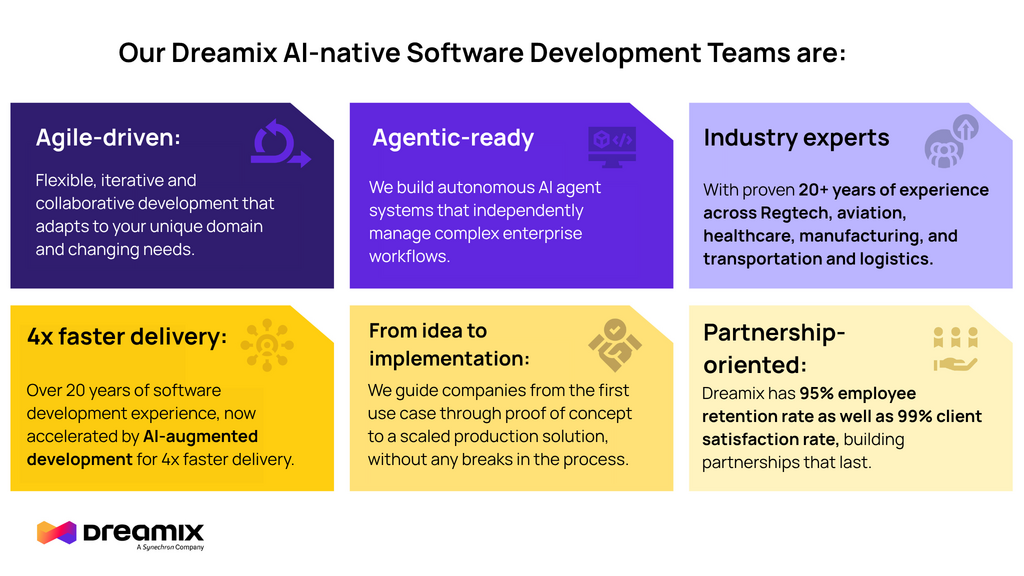
We have been building and modernising software for enterprise partners since 2006, in fintech, aviation, transportation and pharma. Cost work is rarely a standalone engagement for us. It shows up inside modernisation programmes, migrations and product builds, because that is where the durable savings are decided.
If your cloud bill is growing faster than the business it supports, the useful first step is a short assessment: current spend mapped against unit metrics, the recoverable amount quantified, and a sequence for capturing it.
FAQ regarding cloud cost reduction:
We’d love to hear about your cloud cost optimisation challenges and help you meet your business goals as soon as possible.